The Container Was Never the Point

In 2014, we were already suspicious of the container as the unit of deployment. Not because containers were bad; they were obviously useful. But the interesting object was never the tarball, the daemon, or the runtime bundle. The interesting object was the service: what it is, what it needs, what it can talk to, what authority it has, and what execution boundary it actually requires.
A decade later, NixOS and systemd are making that old question feel practical
again. Nix can describe the software artifact. systemd already owns the process
lifecycle, cgroups, resource policy, service identity and a growing amount of
isolation policy. OCI is still an excellent interchange format. If we really do
need something machine-shaped, systemd-nspawn and systemd-vmspawn provide
stronger execution boundaries without making "container" the ontology of the
whole platform.
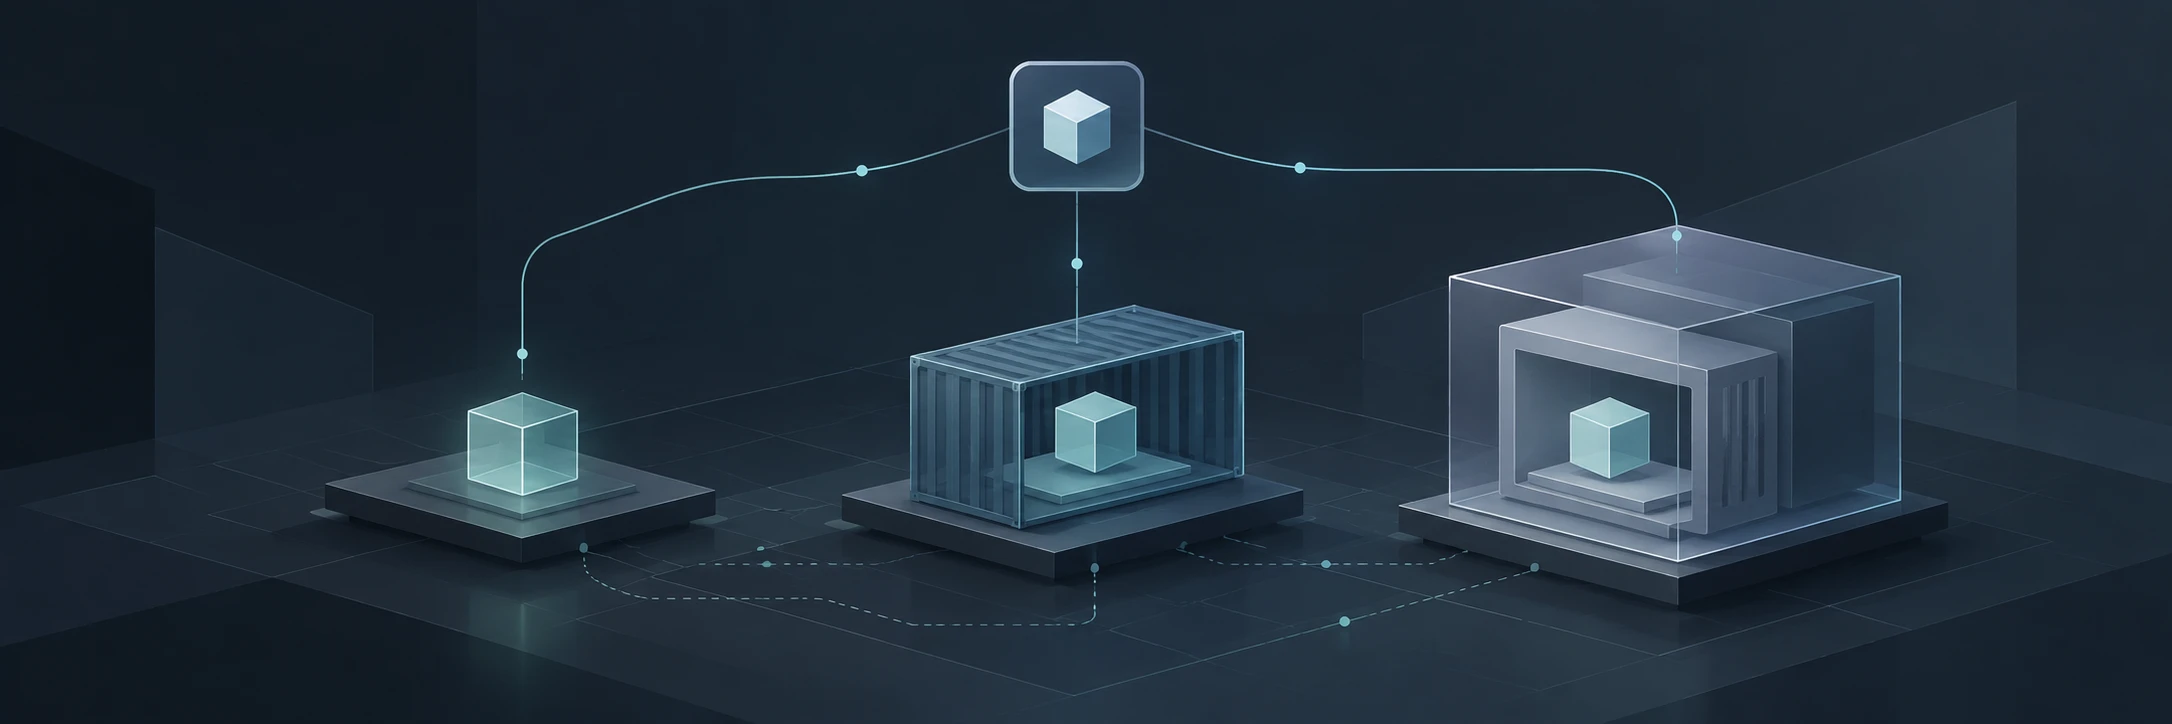
That is the future-facing part of this story: one management model, multiple execution environments. Not everything runs the same way, but increasingly it can be managed the same way. The container was never the point. The service was.
What if docker run is not eventually replaced by a better container runtime?
What if, for a large class of services, it mostly disappears?
This sounds provocative because "container" became the noun that ate the datacenter. We build containers, push containers, scan containers, schedule containers, restart containers, and occasionally sacrifice a small goat to Kubernetes because somebody touched the YAML.
But Linux never had a kernel object called a container.
A container is a composition of mechanisms: namespaces, cgroups, mount trees, capabilities, seccomp, filesystem roots and networking. Docker made those mechanisms into a successful product abstraction. That was genuinely useful. It also trained us to think the box was the thing.
This is the familiar platform pattern. A vendor builds the early integration point because the loose pieces are too hard to use directly. That integration point creates momentum, a market, a vocabulary and a default mental model. Then the ecosystem tries to rescue the useful seam from the platform that first made it legible.
OCI was that rescue attempt. It protocolized the image and runtime boundary, and that mattered. But even a good protocol can become an accidental ontology if we start treating its interchange object as the native shape of all software. The protocol seam is not the system boundary.
In 2026 that assumption is becoming less necessary. A better mental model starts with the service and treats artifact, lifecycle, isolation and machine boundary as separate choices:
                          service
                             |
              +--------------+---------------+
              |              |               |
          artifact       execution        isolation
              |              |               |
             Nix          systemd        namespaces
          closure        lifecycle        cgroups
              |              |            mounts
              |              |            seccomp
              |              |         capabilities
              |              |
              |              +------------+
              |                           |
              |                 need a machine?
              |                           |
              |               +-----------+-----------+
              |               |                       |
              |          systemd-nspawn          systemd-vmspawn
              |          shared kernel           separate kernel
              |               |                       |
              +---------------+-----------+-----------+
                                          |
                                      machined
                                      machinectl
Everything underneath the service is implementation. That is very close to what MatrixOS was trying to build before we had the scars, the tools, or frankly the maturity to build it properly.
Containers were already becoming too many things
Our December 2014 post Docker, Rockets, Mesos and Atlas captured a strange moment in infrastructure history.
Docker had moved beyond the original container runtime into Docker Machine,
Docker Swarm and Docker Compose. CoreOS argued that Docker was trying to own too
much of the stack and started Rocket, later renamed rkt. Mesos was pitching
the datacenter as an operating system. HashiCorp was assembling Vagrant, Packer,
Terraform, Serf and Consul into Atlas.
We wrote at the time:
From Matrix AI's perspective, we would love to have a standardised container specification, as long as all the popular implementations actually implement the spec.
That part aged reasonably well. The specific projects had more mixed fortunes.
rkt ended development in 2020. Apache Mesos was retired to the Apache Attic
in 2025. Kubernetes won the cluster orchestration war, but even Kubernetes
eventually removed its direct Docker Engine integration. Since Kubernetes 1.24,
kubelet talks to CRI-compatible runtimes instead of carrying dockershim.
Docker images survived just fine. Docker as the mandatory center of the stack did not.
This is worth noticing because the long-term result was not one giant container abstraction absorbing everything. It was a collection of interfaces between increasingly independent layers.
OCI became important because it gave us a standardized box. That is exactly what shipping containers are good at. A port in Singapore, a train in Germany and a truck in Texas can all move the same cargo. It does not follow that the factory should keep the goods inside the steel box forever because "container portability."
OCI should be thought about similarly. It is an excellent interchange boundary. It does not have to be the native representation of software after it arrives.
That distinction is where the broader Matrix AI lineage comes back in. Platforms try to make the world legible by pulling decisions into one operating surface. Protocols are more valuable when they create seams: places where independent systems can cooperate without one of them swallowing the others. OCI is useful as a seam. It becomes limiting when every artifact, service boundary and runtime decision has to pretend to be a container-shaped product object.
We ended up calling the thing an Automaton
The older MatrixOS history is more interesting than we remembered. In May 2014, one of our internal notes recorded:
Nix as a Docker provisioner. Can be used to create bare container images as well.
A few months later, the execution unit was being called an
Automaton Container. Then on August 22, 2014, the terminology changed:
Automaton Container => Automaton
That small rename carried a much larger idea. An Automaton was not supposed to mean "a container with a cooler name." The Distributed Lens Architecture work described Automatons as composable units of computation with defined interfaces and dependencies. Architect was intended to reason about those relationships instead of making operators wire together IP addresses and port numbers manually.
The container was only how an Automaton might happen to execute. By July 2015 our notes had become even more explicit:
We may want to use Docker images, but we probably don't want to use the Docker daemon.
The emerging design separated service semantics from artifact construction, runtime execution and network identity:
The Automaton became a service-graph object containing an artifact, dependencies, runtime state, network identity, lifecycle information and, eventually, scheduling and resource information.
That is a much larger abstraction than a Docker image, possibly too large, as we will get to. One part of this architecture became what later R&D notes called a Nix-based graph container.
While reviewing the old work, we have been calling the idea NixContainer, but
the historical term matters. It was not just "build an OCI image with Nix." The
central observation was that Docker and OCI images package files through layers,
while Nix already represents software as a dependency graph of immutable store
objects.
The exact details are more complicated, but the important part is that the runtime dependency structure remains a graph.
So why take that graph, duplicate some of it into filesystem layers, turn those layers into tar archives, push them somewhere, download them again, and unpack them into another filesystem representation if every machine involved already speaks Nix?
Our later MatrixOS implementation had two artifact constructors:
OCIBuildSpec
NixBuildSpec
The OCI path was compatibility. Ark used skopeo and OCI tooling to acquire an
external image, convert it into a runtime bundle, and bring the resulting
artifact into the Nix store as a fixed-output derivation.
The Nix-native path was more interesting. It constructed a small root filesystem
from Nix derivations while preserving references into /nix/store. Hyperspace
exposed the Nix store read-only inside the runtime so those references continued
to work.
The container instance and its artifact were separate things. Hyperspace could
materialize the runtime using OverlayFS, FUSE OverlayFS, or our experimental ZFS
driver, then pass an OCI runtime bundle to runc.
We were not trying to replace OCI; we were trying to put it in its place. OCI was a useful compatibility and runtime boundary. It did not need to become the ontology of the entire platform.
One management model, multiple execution environments
Boring is good. Boring infrastructure is infrastructure somebody else has already spent ten years debugging at 3 AM.
The interesting systemd changes are not that containers suddenly appeared
in 2026. systemd-nspawn, cgroups, service sandboxing, RootDirectory= and
RootImage= have all existed in various forms for years. The change is that
enough of the boring pieces are now lining up that we can start from the service
and choose its execution properties underneath it.
Systemd 260 introduced
RootMStack=,
which lets an ordinary service execute against a mount stack assembled from
layers and bind mounts with OverlayFS. The same release added
importctl pull-oci,
so systemd's image infrastructure can directly acquire OCI images.
That is a fascinating combination. The artifact can arrive as OCI while the running thing remains an ordinary systemd service.
The missing abstraction is not "systemd can also run containers." That is too small. The bigger point is that requesting, supervising and inspecting a workload can be separated from the mechanism used to execute it.
That gives us a more useful set of questions:
| Question | Examples |
|---|---|
| How is the workload requested? | Interactive command, programmatic API, or persistent Nix-generated configuration. |
| Which manager owns its lifecycle? | The system manager or a user's service manager. |
| What executes? | A direct program, a namespace-contained environment, or a VM runner. |
| What supplies its files? | A Nix closure, a directory tree, a disk image, or an imported image. |
| What restrictions apply? | Filesystem visibility, identities, networking, syscalls, devices and resource limits. |
Choosing a different execution boundary should not automatically require choosing a different lifecycle-management system.
That is the convergence worth paying attention to. For ordinary services it is
already part of the furniture: systemd-run creates a transient unit in the
same manager that handles persistent unit files, so a workload launched from the
CLI can still have a name, accounting, resource limits and normal lifecycle
inspection.
That matters because interactive execution is not the sloppy prelude to the "real" declarative deployment. It can be managed from the start. For example, we can build a program with Nix and launch it as a transient user service:
python="$(
  nix build \
    --no-link \
    --print-out-paths \
    nixpkgs#python3
)/bin/python"

systemd-run \
  --user \
  --unit=matrix-lab \
  --pty \
  --collect \
  -p MemoryMax=256M \
  -p NoNewPrivileges=yes \
  "$python" -q
Another terminal can inspect the exact same thing through the normal service manager:
systemctl --user status matrix-lab.service
systemctl --user show matrix-lab.service -p MemoryMax
systemd-cgls --user
That memory limit is cgroup policy, not filesystem isolation, network isolation or a machine boundary. Good: those should be separate choices.
NixOS or Home Manager can instead generate a persistent definition targeting a system or user manager. Declarative does not mean automatically running, and interactive does not mean unmanaged. They are two entry points into the same unit-management model.
This gives us a much healthier workflow than forcing every exploratory process to begin life as twenty lines of YAML and a trip through CI:
Home Manager has another relevant experiment in progress: Modular Services.
A modular service can be defined through home.services, analogous to
system.services in NixOS:
{ pkgs, ... }:

{
  home.services.example = {
    process.argv = [
      "${pkgs.hello}/bin/hello"
    ];
  };
}
The interesting part is not running hello. The interesting part is that
Nixpkgs is experimenting with a service description that is less tightly coupled
to where it lands. Package-provided service modules can potentially be reused
across NixOS and Home Manager.
This work is still explicitly marked as developing. It is not the Automaton reborn, and it does not magically provide scheduling, isolation or distributed composition. But the abstraction is moving in a familiar direction: describe the service first, then decide where and how it runs.
A service, a namespace container and a VM are not three simple rungs on one security ladder. This is where infrastructure vocabulary often tricks us: they are different execution shapes with different boundaries.
A systemd service runs and supervises processes. Its execution environment may
include a different filesystem root and additional restrictions. Setting
RootDirectory= or RootImage= changes the environment in which the program
executes. It does not inherently boot another operating system.
systemd-nspawn is a namespace-container runner. It constructs an environment
with a separate filesystem hierarchy, process namespace, hostname and other
namespace-related boundaries. Its processes still use the host kernel. It can
run a command directly, or, with --boot, start an init system inside that
environment.
A "machine" in machined is not just a bigger container. It is a management
abstraction for an OS instance. It can represent an OS container or a full VM.
An application does not become a machine merely because it has an isolated
filesystem.
systemd-vmspawn starts a VM using QEMU. Instead of placing the workload in
namespaces around the host kernel, it starts an environment with its own guest
kernel. Its directory and image inputs, registration and resource-management
interfaces deliberately resemble those of systemd-nspawn, but the execution
mechanism is different.
The architecture therefore should not be read as a universal security-strength slider running from an ordinary service to a sandbox, an nspawn container and finally a VM:
ordinary service -> sandbox -> nspawn -> VM
The distinction is application execution versus OS-instance execution, with isolation policy specified separately. A VM with extensive host filesystem and device access can be a weaker boundary than people imagine. A namespace container running untrusted code without the right user-namespace configuration can be a bad idea.
A common management interface does not absolve you from understanding the
boundary, but it does let those boundaries participate in a common operational
model. machinectl makes that separation visible by letting us talk to the
thing being managed before committing too hard to how that thing runs.
With suitable images and the corresponding service templates installed, the machine-management layer can choose a runner:
sudo machinectl --runner=nspawn start lab-container
sudo machinectl --runner=vmspawn start lab-vm

machinectl list
machinectl status lab-container lab-vm
The runner selection chooses the execution path. Underneath, it selects the
corresponding systemd-nspawn@... or systemd-vmspawn@... service template,
while the management interface sits above that choice. This does not convert an
arbitrary application image into a bootable VM; it is not magic dust, just a
useful seam.
Shutdown shows the abstraction even better:
sudo machinectl poweroff lab-container
sudo machinectl poweroff lab-vm
The operation has the same purpose, but its implementation is backend-specific.
For a compatible container it can signal the guest init process; for a vmspawn
VM it can request powerdown through QEMU's control path. Same intention,
different machinery.
There are limits, because there are always limits. machinectl shell and
login are not universal shells into arbitrary VMs. A VM needs suitable guest
communication. Registering a machine does not automatically make every internal
service visible to the host.
Still, this is the architecture that matters: containers and VMs can participate in a common machine-management interface while their runners implement the operations appropriate to their actual boundaries.
Upstream has also been moving this model into user scope. machinectl --user
and importctl --user exist, with per-user machined and importd support
introduced in systemd 259. systemd-vmspawn --user followed in systemd 260, and
systemd-nspawn --user followed in systemd 261.
Those switches select the management scope; they are not the same thing as choosing a username inside the guest. This distinction matters more than it first appears because a system-managed service need not run as root. The manager that owns the unit and the credentials used by its process are different settings.
Systemd 260 also made systemd-vmspawn explicitly usable against the user
service manager:
systemd-vmspawn --user --image="${HOME}/vms/test.raw"
Then systemd 261 gave systemd-nspawn the equivalent standalone --user scope:
systemd-nspawn --user --image="${HOME}/machines/test.raw" --boot
There is a small compatibility wrinkle here. --user=NAME historically meant
"run as this user inside the container." In 261 that spelling was renamed to
--uid=NAME, freeing --user to mean what it means elsewhere in systemd: use
the user service-manager scope.
It is a tiny command-line change that represents a larger conceptual cleanup.
As of October 2026, NixOS 26.05 still packages systemd 260, while current
Nixpkgs master has moved to systemd 261. So check the version on the machine
rather than trusting a blog post written by somebody living on nixos-unstable:
systemctl --version

nix eval --raw nixpkgs#systemd.version
Systemd 260 is already enough to acquire an OCI artifact through systemd:
sudo importctl \
  --class=machine \
  pull-oci library/nginx nginx
That command imports an artifact. It does not magically make a random OCI image a bootable machine, and it does not solve image trust beyond what the importer provides. The useful part is the direction of travel: acquisition, filesystem representation and execution are becoming separate concerns. The service itself can be simpler still.
On NixOS, systemd.services.<name>.confinement can construct a private
filesystem root containing the runtime Nix store closure required by a service.
For example:
{ pkgs, ... }:

let
  site = pkgs.writeTextDir "index.html" ''
    <h1>The container was never the point.</h1>
  '';
in
{
  systemd.services.graph-demo = {
    description = "Nix closure backed service";

    confinement = {
      enable = true;
      binSh = null;
      packages = [
        pkgs.python3
        site
      ];
    };

    serviceConfig = {
      ExecStart =
        "${pkgs.python3}/bin/python -m http.server 8080 "
        + "--bind 127.0.0.1 --directory ${site}";

      DynamicUser = true;
      NoNewPrivileges = true;
      MemoryMax = "128M";
    };
  };
}
Then:
sudo nixos-rebuild switch
sudo systemctl start graph-demo
curl http://127.0.0.1:8080/
There is no Dockerfile, no image registry, and no /bin/bash unless we
deliberately put one there. There is also no copy of an arbitrary distribution
filesystem because apparently our HTTP server desperately needed its own
miniature civilization.
Nix computes the required store closure. NixOS constructs the filesystem confinement. systemd owns the service lifecycle and cgroup.
The current NixOS confinement module is filesystem isolation, not a complete container security boundary. Networking and other security controls remain separate concerns, which is exactly the point: they should be separate concerns.
The same outer/inner distinction appears in NixOS containers. The host systemd manager owns the container unit. Inside the container there may be another service manager owning application services.
outer systemd manager
    |
    +-- application.service
    |       |
    |       +-- application process
    |           with selected confinement
    |
    +-- container-owning service
    |       |
    |       +-- nspawn
    |               |
    |               +-- guest init / service manager
    |                       |
    |                       +-- application services
    |
    +-- VM-owning service
            |
            +-- vmspawn -> QEMU
                            |
                            +-- guest kernel
                                    |
                                    +-- guest service manager
                                            |
                                            +-- application services
Suppose a containers.lab declaration defines a NixOS guest containing a
demo.service. These commands address different layers:
# Start the entire NixOS container.
sudo systemctl start container@lab.service

# Inspect the registered machine.
machinectl status lab

# Inspect a service inside the container.
sudo systemctl -M lab status demo.service
The outer manager owns the lifetime of the execution environment. The inner manager, when present, owns the services inside it.
There is one refinement to "everything is a service": some executions are
tracked in .scope units instead. A service manager starts a service's
processes. A scope groups and manages processes started externally. Both
participate in systemd's unit and resource-management model, but a scope is not
a service with all the same restart behavior.
So the more accurate claim is not that everything literally becomes a
.service, but that more execution environments can participate in the same
unit-management model.
We had a name for this in MatrixOS: first-class orchestration. The orchestrator was not meant to be one privileged point standing outside the system and issuing special commands into it. Orchestration itself was meant to be a composable functional value: something with a defined scope, authority, inputs and outputs that could be passed, nested and combined like any other module. A common management model mattered because it let those orchestration values act on ordinary managed objects instead of escaping into a separate control substrate.
We were too early, but that is not much of an excuse
There is a flattering version of the MatrixOS story where we were visionaries and everybody finally caught up. That is not the useful version.
We had identified an interesting abstraction, but identifying an abstraction and building the system are different problems. We were trying to build a Nix-backed, OCI-compatible distributed service graph where an Automaton was simultaneously a reproducible artifact, runtime bundle, network identity, dependency node, lifecycle object, monitoring target and scheduling target.
Doing that properly required deep production experience in build systems, Linux container internals, filesystems, networking, distributed systems, programming language design, security and operations.
We were learning many of those things while simultaneously trying to invent the abstraction above them. The ecosystem was immature, and frankly, so were we.
This was the builder's trap in infrastructure form. Every time we solved one piece, the next layer underneath became visible and tempting. Artifact construction wanted closure transport. Runtime bundles wanted filesystem drivers. Filesystem drivers wanted isolation policy. Isolation policy wanted network identity. Network identity wanted service semantics. Service semantics wanted scheduling. Scheduling wanted distributed desired-state reconciliation.
The abstraction was pulling us upward while the missing complements kept pulling us downward. That is how a service model becomes a platform tar pit.
Our old libcontainer experiment is a useful example. We wanted to bind the Go
library directly into Haskell because calling a command-line process felt
inelegant. After digging far enough into libcontainer, we discovered that its
startup model assumed process re-execution and privilege-bracketing behavior
that made our FFI design increasingly hazardous.
Eventually we abandoned the clever binding and called the runtime through its supported command-line interface. This was the correct decision. Sometimes "just execute the process" is not technical defeat; sometimes it is an interface boundary telling you to stop being clever.
We also tried to advance too many research fronts at once. Architect wanted typed service composition and session types. Relay wanted service-centric networking and transparent migration. Overwatch wanted protocol specifications to generate BPF monitoring. Cybergraph wanted distributed incremental desired-state reconciliation. Prime wanted to optimize the whole configuration graph. Emergence had to actually make the thing run.
The architecture was coherent on a whiteboard. Unfortunately computers insist on executing the implementation rather than the whiteboard.
Our later Ouroboros end-to-end experiment was useful precisely because it forced us back down to earth. Trying to orchestrate one real HTTP service exposed unresolved questions in the Automaton and Cybergraph data models. We ended up deprioritizing some of the more ambitious session-type and BPF work until the basic service lifecycle and desired-state representation became clearer.
We should have forced that feedback loop much earlier. Three lessons from that experience still matter:
- The highest abstraction should not require you to own every layer below it. MatrixOS needed to understand Linux networking and runtime isolation, but that did not mean it needed to replace every networking and runtime subsystem.
- Standards are most useful as seams. OCI became valuable precisely because the ecosystem stopped requiring one vendor's daemon to own image format, execution and orchestration at the same time.
- Boring infrastructure changes what is worth inventing.
In 2014, getting from a reproducible artifact to an isolated process, connecting it to a network, and managing its lifecycle meant choosing immature projects or building significant parts ourselves.
In 2026, Nix already gives us reproducible closures. systemd gives us service lifecycle, cgroups, namespaces, resource controls, filesystem roots, container execution, VM execution, machine management and increasingly useful user-scoped versions of those mechanisms. OCI gives us a standard interchange format.
That does not solve the original MatrixOS problem; it moves the problem upward.
MatrixOS wanted to describe a service independently of its artifact representation, execution mechanism and placement while retaining one coherent lifecycle model. Much more of the local execution and management layer can now be delegated to existing infrastructure. That still does not decide distributed placement, validate service-interface compatibility, coordinate application state across machines, or produce verifiable evidence about what happened.
Those are higher-level protocol questions, and they are also the questions worth spending invention on.
The interesting questions are again the questions the Automaton was supposed to answer:
What is this service?

What interfaces does it provide?

What does it depend on?

What authority does it possess?

What state belongs to it?

Where may it run?

What execution boundary does it actually require?
And increasingly:
What evidence does it produce?

Who can rely on that evidence?

Which parts of its lifecycle are local operations,
and which parts are protocol commitments?
Maybe the answer underneath is an ordinary process, a filesystem-confined
systemd service, an nspawn container, or a VM. Maybe somewhere in a Kubernetes
cluster it really should be a Pod. The service should not care any more than
necessary. That was the point of the Automaton.
We tried to build too much of the future underneath it ourselves. A decade later, enough of that future has become boring Linux plumbing that the idea is worth looking at again. The execution mechanism changes; the management model does not have to. The service is the coordination boundary: identity, authority, interfaces, state, placement, lifecycle and eventually evidence. The container is only one possible execution policy beneath that boundary.
The container was never the point. The service was.